3D Cuboid Annotation
Position, dimension and orientation — not just a flat rectangle
3D cuboid annotation adds depth to detection. Each object gets a box with real dimensions and a heading angle, so your model learns where an object is in space and which way it is facing — the foundation of any autonomy or spatial-reasoning stack.
- Starting at
- $0.18 / cuboid
- Turnaround
- 48–96 hours
- Quality
- ±3° orientation accuracy
Human-labelled
Reviewed twice before delivery
2D detection can't tell you how far away or which way
A flat box says a car is somewhere in the frame. It cannot say the car is 14 metres ahead, angled 30° across your lane and about to cut in.
We annotate cuboids with consistent dimension priors per class and validate heading against motion direction across sequential frames.
Send us a sample batchWhat is 3D cuboid annotation?
A cuboid is a 3D bounding box defined by centre position, length, width, height and yaw. On camera imagery it is projected onto the frame; with LiDAR it is placed directly in point-cloud space.
It is the standard representation for object detection in autonomous driving, warehouse robotics and any system that has to plan a path around real objects.
Where it's used
Built for real production pipelines
Autonomous vehicles
Vehicles, pedestrians and cyclists with heading and dimensions.
LiDAR point-cloud labelling
Cuboids placed in 3D space and synced with camera frames.
Warehouse & logistics robotics
Pallets, bins and forklifts for navigation and pick planning.
Construction & heavy equipment
Machinery and material tracking on active sites.
Sample work
Raw frame in, training-ready labels out
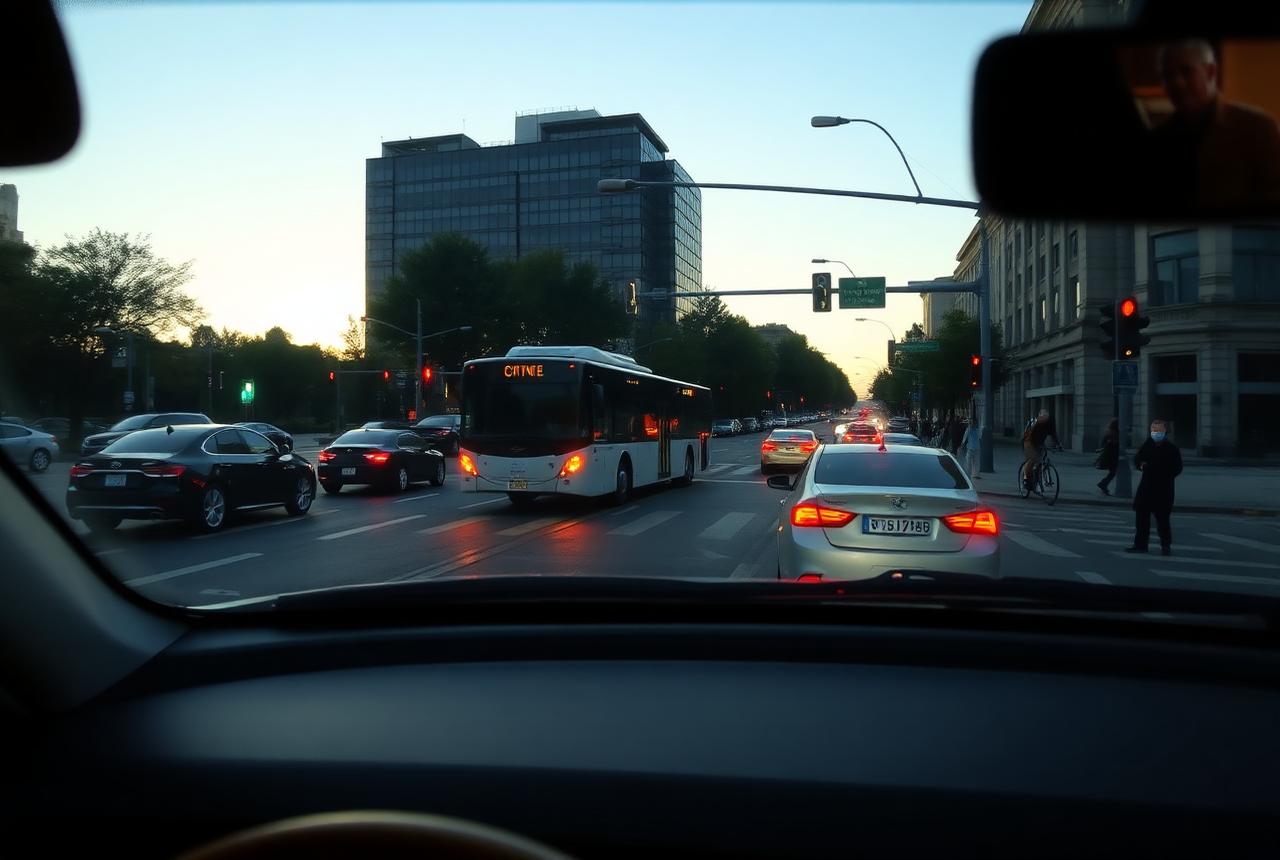
Real 3d cuboid annotation output from client pilots. Drag the handle on any example to compare the source frame with what we deliver.
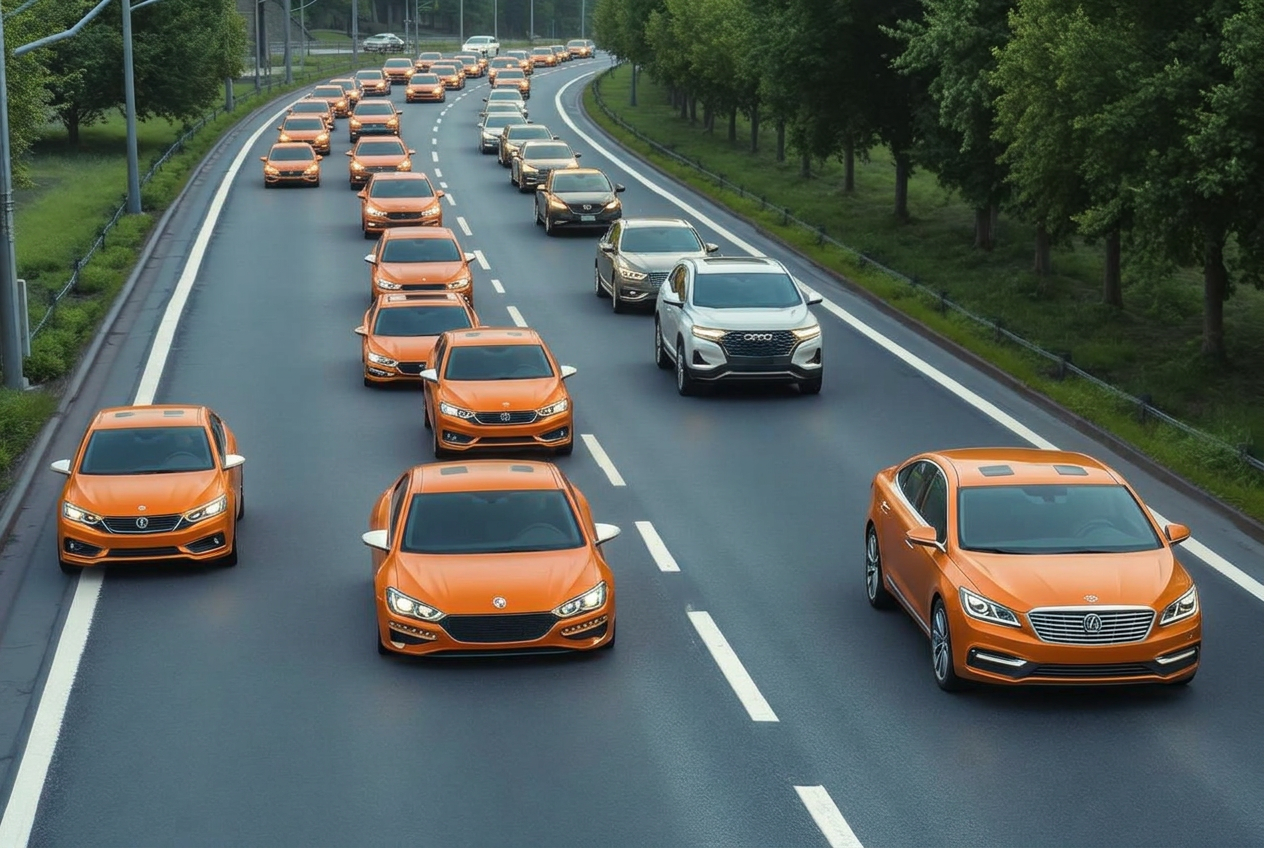 Before
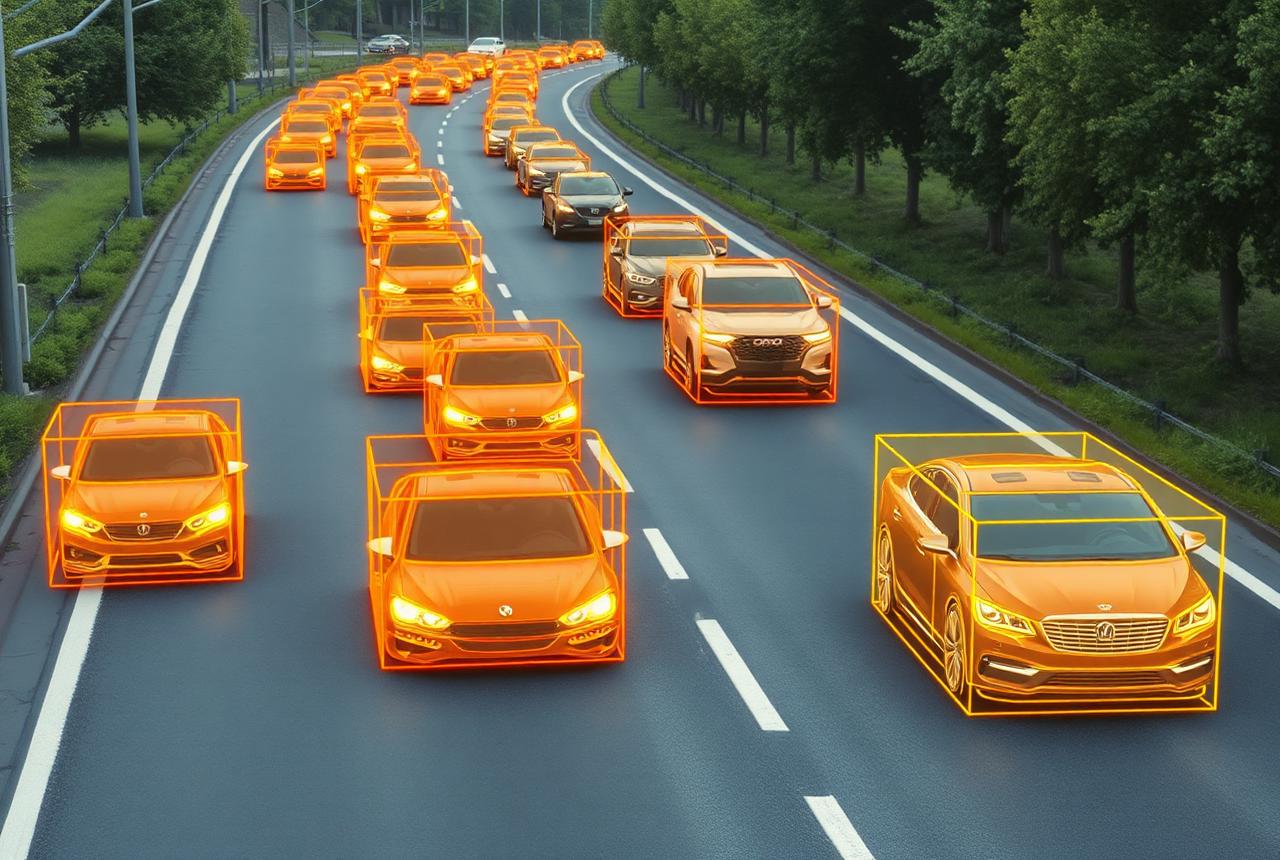
Highway fleet tracking
3D cuboids fitted to vehicles with correct heading and dimension, so downstream models estimate distance and orientation instead of just 2D position.
Orientation + dimension · 96% cuboid IoU · KITTI
 Before
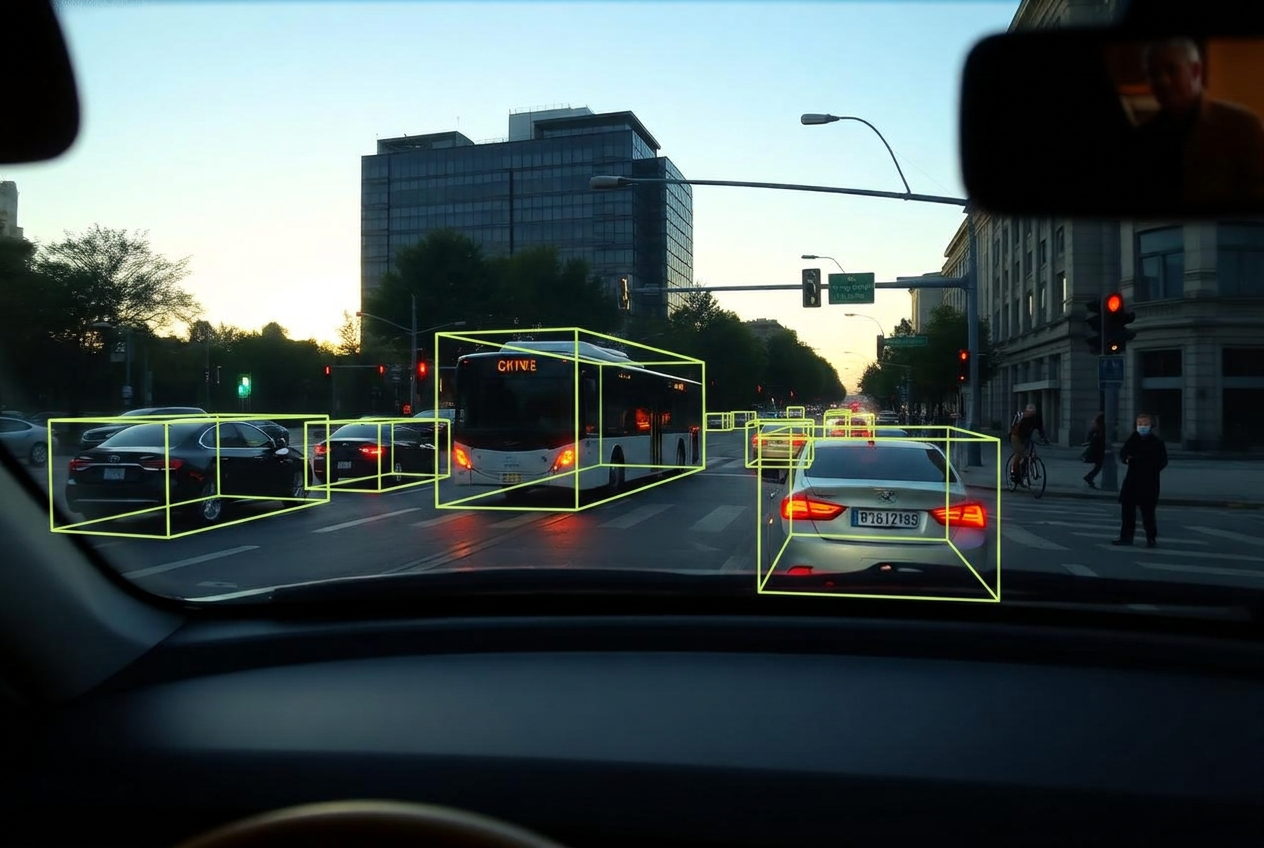
Dashcam intersection scene
Low-light dusk frame with a bus, cars and cyclists cuboided in perspective — including partially visible vehicles at the crossing, which most vendors skip.
6 classes · yaw annotated · KITTI + custom JSON
Samples are representative of delivered work; client-identifying frames are replaced under NDA.
How we work
A spec, a pilot, then volume — in that order
Most labelling projects fail on ambiguity, not effort. We remove the ambiguity first, prove it on a pilot, and only then scale throughput.
Start with a free pilot- 1
Sensor & format review
We confirm calibration, coordinate system and export target before touching data.
- 2
Pilot sequence
One full sequence annotated and reviewed with your perception engineer.
- 3
Production pods
Trained 3D annotators work sequences end to end so tracking stays consistent.
- 4
Fusion QA
Cuboids re-projected onto camera frames to catch depth errors visually.
Quality control
- Dimension-prior conformance per class
- Heading validation across frames
- Camera–LiDAR projection check
- Specialist re-review on hard frames
What you receive
- KITTI format
- nuScenes JSON
- Point-cloud PCD annotations
- Sensor-fusion aligned exports
Tools we work in
- CVAT 3D
- Segments.ai
- Supervisely
- Client tooling via VPN
This is for you if…
AV and ADAS teams building perception stacks
Robotics companies fusing camera and LiDAR data
Anyone needing distance and orientation, not just presence
Every project runs under NDA with access-controlled workstations. Data is deleted on request after delivery.
Why teams switch
You have three options. Only one of them scales.
Hire in-house
- 6–10 weeks to recruit and train
- Fixed salary cost at variable volume
- QA falls on your ML engineers
Random freelancers
- Every batch looks slightly different
- No written spec, no review pass
- Disappear mid-project
Genius Clipping Path
- Dedicated pod trained on your written spec
- Two-pass QA on every single batch
- Pay per unit — scale up or pause anytime
Simple commercials
Pick the engagement that fits your stage
Pilot
Free
Up to 50 items annotated to your spec so you can benchmark quality before spending anything.
Pay per unit
$0.18 / cuboid
Send batches whenever you need them. No minimums, no retainers, invoiced monthly.
Dedicated pod
Monthly
A fixed team reserved for your queue with guaranteed daily throughput and a named QA lead.
Not sure which fits? Tell us the dataset size below and we'll recommend the cheapest option that hits your deadline — even if that's the free pilot only.
Talk to us
Get a 3d cuboid annotation quote — and a free pilot with it
Send your label spec and dataset size. You'll get a per-unit price, a realistic delivery date, and 50 annotated samples so you can judge quality before committing a cent.
- A real annotation specialist replies — not a sales bot
- Free 50-item pilot annotated to your written spec
- NDA signed before we touch your data
- No minimum volume and no lock-in contract
Prefer email? Write to support@geniusclippingpath.com and attach a few sample frames.
Before you get in touch
3D Cuboid Annotation FAQs
Pricing, guidelines, security, rework and export formats — the answers teams usually ask for on the first call.
Do you work directly in point clouds?+
Yes — LiDAR-native cuboid placement with camera-frame verification, or camera-only cuboids where no point cloud exists.
Which export formats do you support?+
KITTI, nuScenes, Waymo-style JSON, or a custom schema we map to your loader.
Can you maintain object IDs across a sequence?+
Yes. Sequences are assigned to one annotator so track IDs stay stable across the whole clip.
Can we run a free pilot before committing?+
Yes. Send 50–100 representative images and we label them free against your guideline draft, usually within 24 hours, so you can measure quality on your own data before any invoice.
How do you handle our annotation guidelines?+
You can send an existing spec or start from a call. We turn it into a written guideline with edge-case examples, get your sign-off, and every annotator is trained and tested against it.
What happens if labels come back wrong?+
Rework is free. Flag the batch within 7 days of delivery, we correct the affected items and update the guideline so the same error class does not repeat.
How do you keep our data secure?+
NDAs on request, access-controlled workstations, no personal devices or external storage, project-scoped access per annotator, and permanent deletion after delivery when you ask for it.
Which export formats do you deliver?+
COCO JSON, YOLO txt, Pascal VOC XML, KITTI, CSV, or masks as PNG. If you use a custom schema or a platform like Labelbox, CVAT, or V7, we deliver straight into it.
How fast can you scale up?+
A dedicated pod starts at 3 annotators and scales to 100+ within about a week, with a QA lead assigned to your project throughout so quality holds as volume grows.
How does billing work?+
Pay per unit with volume tiers, or a fixed monthly dedicated-pod rate. You get an itemised invoice per batch, no setup fee, and no minimum contract on pay-per-unit work.
Still unsure? Ask us anything — we reply within one hour on business days.
Get a quoteOther annotation services
Bounding Box Annotation
2D boxes for fast, reliable object detection training data.
Polygon Annotation
Pixel-tight outlines for irregular, overlapping objects.
Semantic Segmentation
Pixel-level class labels across the whole scene.
Keypoint & Landmark Annotation
Pose, face and skeleton points placed with precision.
Image Classification & Tagging
Clean taxonomies and consistent tags across huge datasets.
Try 3d cuboid annotation on your own data — free
Send 50 sample frames and your label spec. You get a fully annotated, QA-reviewed pilot back within 24 hours. No card, no commitment.